on master help sign in
Merge pull request #1391 from urbit/add-full-stack-walkthrough
c0c5945tinnus-napbus
content/docs/arvo/clay/marks/_index.md+1−1
@@ -12,7 +12,7 @@ Overview of `mark`s.
12
12
13[Writing Marks](/docs/arvo/clay/marks/writing-marks)
14
14
15−A practical walk-through of writing a `mark` file.
15+A practical walkthrough of writing a `mark` file.
16
16
17[Using Marks](/docs/arvo/clay/marks/using-marks)
18
18
content/docs/arvo/clay/marks/marks.md+1−1
@@ -52,7 +52,7 @@ The second case of interest is the `+json` arm for converting to and from a `%js
52
52
53## Sections
53## Sections
54
54
55−[Writing Marks](/docs/arvo/clay/marks/writing-marks) - A practical walk-through of writing a `mark` file.
55+[Writing Marks](/docs/arvo/clay/marks/writing-marks) - A practical walkthrough of writing a `mark` file.
56
56
57[Using Marks](/docs/arvo/clay/marks/using-marks) - Details of using `mark` conversion gates and `mark` cores in your own code.
58
58
content/docs/userspace/dist/dist.md+1−1
@@ -6,7 +6,7 @@ template = "doc.html"
6
6
7Urbit allows peer-to-peer distribution and installation of applications. A user can click on a link to an app hosted by another ship to install that app. The homescreen interface lets users manage their installed apps and launch their interfaces in new tabs.
8
8
9−This document describes the architecture of Urbit's app distribution system. For a walk-through of creating and distributing an app, see the [`Guide`](/docs/userspace/dist/guide) document.
9+This document describes the architecture of Urbit's app distribution system. For a walkthrough of creating and distributing an app, see the [`Guide`](/docs/userspace/dist/guide) document.
10
10
11## Architecture
11## Architecture
12
12
content/docs/userspace/full-stack/1-intro.mdnew file+89
@@ -0,0 +1,89 @@
1++++
2+title = "1. Introduction"
3+weight = 1
4+template = "doc.html"
5++++
6+
7+This series walks through the writing of a full Gall agent, and then the process
8+of integrating it with a React front-end. This series follows on from the
9+previous [Gall Guide](/docs/userspace/gall-guide/intro). If you haven't
10+completed that, or otherwise aren't familiar with the basics of writing Gall
11+agents, it's strongly recommended to work through that guide first.
12+
13+The app we'll be looking at is a simple journal with an agent called `%journal`.
14+In the browser, users will be able to add plain text journal entries organized
15+by date. Entries may be scrolled through in ascending date order, with more
16+entries loaded each time the bottom of the list is reached. Old entries will be
17+able to be edited and deleted, and users will be able to search through entries
18+by specifying a date range.
19+
20+The `Journal` app we'll be looking at can be installed on a live ship from
21+`~pocwet/journal`, and its source code is available [here](https://github.com/urbit/docs-examples/tree/main/journal-app).
22+
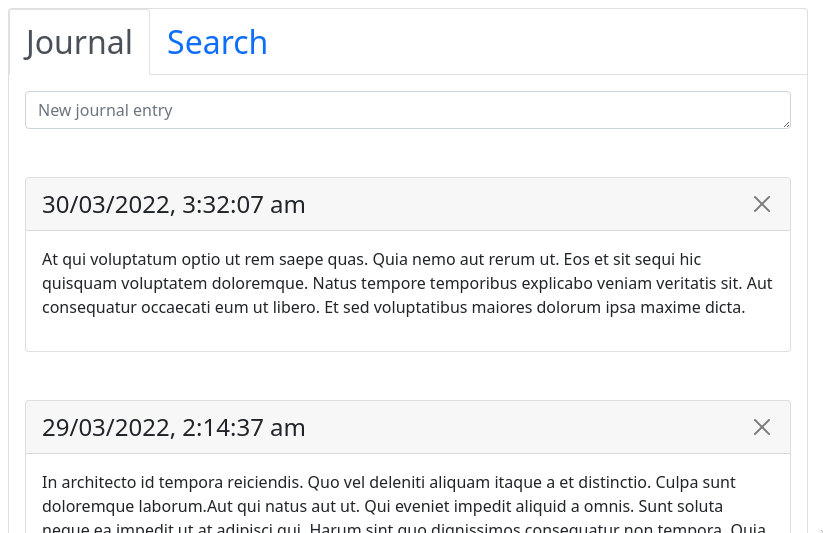
23+![journal ui screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/entries.png)
24+
25+This walkthrough does not contain exercises, nor does it completely cover every
26+aspect of building the app in full depth. Rather, its purpose is to demonstrate
27+the process of creating a full-stack Urbit app, showing how everything fits
28+together, and how concepts you've previously learned are applied in practice.
29+
30+The primary focus of the walkthrough is to show how a Javascript front-end is
31+integrated with a Gall agent and distributed as a complete app. Consequently,
32+the example app is fairly simple and runs on a local ship only, rather than one
33+with more complex inter-ship networking.
34+
35+Each section of this walkthrough will list additional resources and learning
36+material at the bottom of the page, which will cover the concepts discussed in a
37+more comprehensive manner.
38+
39+Here is the basic structure of the app we'll be building:
40+
41+![journal app
42+diagram](https://media.urbit.org/docs/userspace/full-stack-guide/journal-app-diagram.svg)
43+
44+## Sections
45+
46+#### [1. Introduction](/docs/userspace/gall-2/1-intro)
47+
48+An overview of the guide and table of contents.
49+
50+#### [2. Types](/docs/userspace/gall-2/2-types)
51+
52+Creating the `/sur` structure file for our `%journal` agent.
53+
54+#### [3. Agent](/docs/userspace/gall-2/3-agent)
55+
56+Creating the `%journal` agent itself.
57+
58+#### [4. JSON](/docs/userspace/gall-2/5-json)
59+
60+Writing a library to convert between our agent's marks and JSON. This lets our
61+React front-end poke our agent, and our agent send updates back to it.
62+
63+#### [5. Marks](/docs/userspace/gall-2/4-marks)
64+
65+Creating the mark files for the pokes our agent takes and updates it sends out.
66+
67+#### [6. Eyre](/docs/userspace/gall-2/6-eyre)
68+
69+A brief overview of how the webserver vane Eyre works.
70+
71+#### [7. React App Setup](/docs/userspace/gall-2/7-react-setup)
72+
73+Creating a new React app, installing the required packages, and setting up some
74+basic things for our front-end.
75+
76+#### [8. React App Logic](/docs/userspace/gall-2/8-http-api)
77+
78+Analyzing the core logic of our React app, with particular focus on using
79+methods of the `Urbit` class from `@urbit/http-api` to communicate with our
80+agent.
81+
82+#### [9. Desk and Glob](/docs/userspace/gall-2/9-web-scries)
83+
84+Building and "globbing" our front-end, and putting together a desk for
85+distribution.
86+
87+#### [10. Summary](/docs/userspace/gall-2/10-final)
88+
89+Some final comments and additional resources.
content/docs/userspace/full-stack/10-final.mdnew file+118
@@ -0,0 +1,118 @@
1++++
2+title = "10. Summary"
3+weight = 10
4+template = "doc.html"
5++++
6+
7+That's it! We've built our agent and React front-end, put together a desk and
8+published it. We hope this walkthrough has helped you see how all the pieces
9+for together for building and distributing an app in Urbit.
10+
11+The reference material for each section of this walkthrough is listed
12+[below](#reference-material), the source code for our app is available
13+[here](https://github.com/urbit/docs-examples/tree/main/journal-app), and it can
14+be installed from `~pocwet/journal`.
15+
16+In this guide we've built a separate React app for the front-end, but Hoon also
17+has a native domain-specific language for composing HTML structures called Sail.
18+Sail allows you to compose a front-end inside a Gall agent and serve it
19+directly. See the [Sail guide](/docs/hoon/guides/sail) for details.
20+
21+Along with `@urbit/http-api`, there's also the `@urbit/api` NPM package, which
22+contains a large number of helpful functions for dealing with Hoon data types
23+and interacting with a number of agents - particularly those used by the Groups
24+app. Its source code is [available
25+here](https://github.com/urbit/urbit/tree/master/pkg/npm/api).
26+
27+## Reference material
28+
29+Here is the reference material for each section of this walkthrough.
30+
31+#### Types
32+
33+- [Gall Guide /sur section](/docs/userspace/gall-guide/7-sur-and-marks#sur) -
34+ This section of the Gall Guide covers writing a `/sur` structure library for
35+ an agent.
36+
37+- [Ordered map functions in
38+ `zuse.hoon`](https://github.com/urbit/urbit/blob/master/pkg/arvo/sys/zuse.hoon#L5284-L5688) -
39+ This section of `zuse.hoon` contains all the functions for working with
40+ `mop`s, and is well commented.
41+
42+#### Agent
43+
44+- [The Gall Guide](/docs/userspace/gall-guide/intro) - The Gall Guide covers all
45+ aspects of writing Gall agents in detail.
46+
47+- [Ordered map functions in
48+ `zuse.hoon`](https://github.com/urbit/urbit/blob/master/pkg/arvo/sys/zuse.hoon#L5284-L5688) -
49+ This section of `zuse.hoon` contains all the functions for working with
50+ `mop`s, and is well commented.
51+
52+- [`/lib/agentio.hoon`](https://github.com/urbit/urbit/blob/master/pkg/base-dev/lib/agentio.hoon) -
53+ The `agentio` library in the `%base` desk contains a large number of useful
54+ functions which making writing Gall agents easier.
55+
56+#### JSON
57+
58+- [The JSON Guide](/docs/hoon/guides/json-guide) - The stand-alone JSON guide
59+ covers JSON encoding/decoding in great detail.
60+- [The Zuse Reference](/docs/hoon/reference/zuse/table-of-contents) - The
61+ `zuse.hoon` reference documents all JSON-related functions in detail.
62+
63+- [`++enjs:format` reference](/docs/hoon/reference/zuse/2d_1-5#enjsformat) -
64+ This section of the `zuse.hoon` documentation covers all JSON encoding
65+ functions.
66+
67+- [`++dejs:format` reference](/docs/hoon/reference/zuse/2d_6) - This section of
68+ the `zuse.hoon` documentation covers all JSON _decoding_ functions.
69+
70+- [Eyre Overview](/docs/arvo/eyre/eyre) - This section of the Eyre vane
71+ documentation goes over the basic features of the Eyre vane.
72+
73+#### Marks
74+
75+- [The Marks section of the Clay documentation](/docs/arvo/clay/marks/marks) -
76+ This section of the Clay vane documentation covers mark files comprehensively.
77+- [The mark file section of the Gall
78+ Guide](/docs/userspace/gall-guide/7-sur-and-marks#mark-files) - This part of
79+ the Gall Guide goes through the basics of mark files.
80+
81+- [The JSON Guide](/docs/hoon/guides/json-guide) - This also covers writing mark
82+ files to convert to/from JSON.
83+
84+#### Eyre
85+
86+- [The Eyre vane documentation](/docs/arvo/eyre/eyre) - This section of the vane
87+ docs covers all aspects of Eyre.
88+- [Eyre External API Reference](/docs/arvo/eyre/external-api-ref) - This section
89+ of the Eyre documentation contains reference material for Eyre's external API.
90+
91+- [The Eyre Guide](/docs/arvo/eyre/guide) - This section of the Eyre
92+ documentation walks through using Eyre's external API at a low level (using
93+ `curl`).
94+
95+#### React App Setup and Logic
96+
97+- [HTTP API Guide](/docs/userspace/http-api-guide) - Reference documentation for
98+ `@urbit/http-api`.
99+
100+- [React app source
101+ code](https://github.com/urbit/docs-examples/tree/main/journal-app/ui) - The
102+ source code for the Journal app UI.
103+
104+- [`@urbit/http-api` source
105+ code](https://github.com/urbit/urbit/tree/master/pkg/npm/http-api) - The
106+ source code for the `@urbit/http-api` NPM package.
107+
108+#### Desk and Glob
109+
110+- [App publishing/distribution docs](/docs/userspace/dist/dist) -
111+ Documentation covering third party desk composition, publishing and
112+ distribution.
113+
114+- [Glob documentation](/docs/userspace/dist/glob) - Comprehensive documentation
115+ of handling front-end files.
116+
117+- [Desk publishing guide](/docs/userspace/dist/guide) - A step-by-step guide to
118+ creating and publishing a desk.
content/docs/userspace/full-stack/2-types.mdnew file+215
@@ -0,0 +1,215 @@
1++++
2+title = "2. Types"
3+weight = 2
4+template = "doc.html"
5++++
6+
7+The best place to start when building a new agent is its type definitions in its
8+`/sur` structure file. The main things to think through are:
9+
10+1. What basic types of data does my agent deal with?
11+2. What actions/commands does my agent need to handle?
12+3. What updates/events will my agent need to send out to subscribers?
13+4. What does my agent need to store in its state?
14+
15+Let's look at each of these questions in turn, and put together our agent's
16+`/sur` file, which we'll call `/sur/journal.hoon`.
17+
18+### 1. Basic types
19+
20+Our journal entries will just be plain text, so a simple `@t` will work fine to
21+store their contents. Entries will be organized by date, so we'll also need to
22+decide a format for that.
23+
24+One option would be to use an `@da`, and then use the date functions included
25+in the `@urbit/api` NPM package on the front-end to convert them to ordinary
26+Javascript `Date` objects. In this case, to keep it simple, we'll just use the
27+number of milliseconds since the Unix Epoch as an `atom`, since it's natively
28+supported by the Javascript `Date` object.
29+
30+The structure for a journal entry can therefore be:
31+
32+```hoon
33++$ id @
34++$ txt @t
35++$ entry [=id =txt]
36+```
37+
38+### 2. Actions
39+
40+Now that we know what a journal entry looks like, we can think about what kind
41+of actions/commands our agent will handle in its `++on-poke` arm. For our
42+journal app, there are three basic things we might do:
43+
44+1. Add a new journal entry.
45+2. Edit an existing journal entry.
46+3. Delete an existing journal entry.
47+
48+We can create a tagged union structure for these actions, like so:
49+
50+```hoon
51++$ action
52+ $% [%add =id =txt]
53+ [%edit =id =txt]
54+ [%del =id]
55+ ==
56+```
57+
58+### 3. Updates
59+
60+Updates are a little more complicated than our actions. Firstly, our front-end
61+needs to be able to retrieve an initial list of journal entries to display. Once
62+it has that, it also needs to be notified of any changes. For example, if a new
63+entry is added, it needs to know so it can add it to the list it's displaying.
64+If an entry gets deleted, it needs to remove it from the list. Etc.
65+
66+The simplest approach to the initial entries is just a `(list entry)`. Then, for
67+the subsequent updates, we could send out the `$action`. Since an `$action` is a
68+tagged union, it's simpler to have all updates be a tagged union, so when we get
69+to doing mark conversions we can just switch on the head tag. Therefore, we can
70+define an `$update` structure like so:
71+
72+```hoon
73++$ update
74+ $% action
75+ [%jrnl list=(list entry)]
76+ ==
77+```
78+
79+There's one drawback to this structure. Suppose either an agent on a remote ship
80+or an instance of the front-end client is subscribed for updates, and the
81+network connection is disrupted. In the remote ship case, Gall will only allow
82+so many undelivered messages to accumulate in Ames before it automatically kicks
83+the unresponsive subscriber. In the front-end case, the subscription will also
84+be ended if enough unacknowledged messages accumulate, and additionally the
85+client may sometimes need to establish an entirely new connection with the ship,
86+discarding existing subscriptions. When this happens, the remote ship or web
87+client has no way to know how many (if any) updates they've missed.
88+
89+The only way to resynchronize their state with ours is to discard their existing
90+state, refetch the entire initial state once again, and then resubscribe for
91+updates. This might be fine if the state of our agent is small, but it becomes a
92+problem if it's very large. For example, if our agent holds tens of thousands of
93+chat messages, having to resend them all every time anyone has connectivity
94+issues is quite inefficient.
95+
96+One solution to this is to keep an _update log_. Each update can be tagged with
97+the time it occurred, and stored in our agent's state, separately to the
98+entries. If an agent or web client needs to resynchronize with our agent, it can
99+just request all updates since the last one it received. This approach is used
100+by the `%graph-store` agent, for example. Our agent is local-only and doesn't
101+have a huge state so it might not be strictly necessary, but we'll use it to
102+demonstrate the approach.
103+
104+We can define a logged update like so, where the `@` is the update timestamp in
105+milliseconds since the Unix Epoch:
106+
107+```hoon
108++$ logged (pair @ action)
109++$ update
110+ %+ pair @
111+ $% action
112+ [%jrnl list=(list entry)]
113+ [%logs list=(list logged)]
114+ ==
115+```
116+
117+### 4. State
118+
119+We need to store two things in our state: the journal entries and the update
120+log. We could just use a couple of `map`s like so:
121+
122+```hoon
123++$ journal (map id txt)
124++$ log (map @ action)
125+```
126+
127+Ordinary `map`s are fine if we just want to access one value at a time, but we
128+want to be able to:
129+
130+1. Retrieve only some of the journal entries at a time, so we can have "lazy
131+ loading" in the front-end, loading more entries each time the user scrolls to
132+ the bottom of the list.
133+2. Retrieve only logged updates newer than a certain time, in the case where the
134+ subscription is interrupted due to connectivity issues.
135+3. Retrieve journal entries between two dates.
136+
137+Maps are ordered by the hash of their key, so if we convert them to a list
138+they'll come out in seemingly random order. That means we'd have to convert the
139+map to a list, sort the list, and then iterate over it again to pull out the
140+items we want. We could alternatively store things in a list directly, but
141+retrieving or modifying arbitrary items would be less efficient.
142+
143+To solve this, rather than using a `map` or a `list`, we can use an _ordered
144+map_. The mold builder for an ordered map is a `mop`, and it's included in the
145+[`zuse.hoon`](https://github.com/urbit/urbit/blob/master/pkg/arvo/sys/zuse.hoon#L5284)
146+utility library rather than the standard library.
147+
148+A `mop` is defined similarly to a `map`, but it takes an extra argument in the
149+following manner:
150+
151+```hoon
152+((mop key-mold val-mold) comparator-gate)
153+```
154+
155+The gate is a binary gate which takes two keys and produces a `?`. The
156+comparator is used to decide how to order the items in the mop. In our case,
157+we'll create a `$journal` and `$log` `mop` like so:
158+
159+```hoon
160++$ journal ((mop id txt) gth)
161++$ log ((mop @ action) lth)
162+```
163+
164+The entries in `$journal` are arranged in ascending time order using `++gth`, so
165+the right-most item is the newest. The `$log` `mop` contains the update log, and
166+is arranged in descending time order, so the right-most item is the oldest.
167+
168+We'll look at how to use ordered maps later when we get to writing the agent
169+itself.
170+
171+## Conclusion
172+
173+When we put each of these parts together, we have our complete
174+`/sur/journal.hoon` file:
175+
176+```hoon
177+|%
178+:: Basic types of the data we're dealing with
179+::
180++$ id @
181++$ txt @t
182++$ entry [=id =txt]
183+:: Poke actions
184+::
185++$ action
186+ $% [%add =id =txt]
187+ [%edit =id =txt]
188+ [%del =id]
189+ ==
190+:: Types for updates to subscribers or returned via scries
191+::
192++$ logged (pair @ action)
193++$ update
194+ %+ pair @
195+ $% action
196+ [%jrnl list=(list entry)]
197+ [%logs list=(list logged)]
198+ ==
199+:: Types for our agent's state
200+::
201++$ journal ((mop id txt) gth)
202++$ log ((mop @ action) lth)
203+--
204+```
205+
206+## Resources
207+
208+- [Gall Guide /sur section](/docs/userspace/gall-guide/7-sur-and-marks#sur) -
209+ This section of the Gall Guide covers writing a `/sur` structure library for
210+ an agent.
211+
212+- [Ordered map functions in
213+ `zuse.hoon`](https://github.com/urbit/urbit/blob/master/pkg/arvo/sys/zuse.hoon#L5284-L5688) -
214+ This section of `zuse.hoon` contains all the functions for working with
215+ `mop`s, and is well commented.
content/docs/userspace/full-stack/3-agent.mdnew file+338
@@ -0,0 +1,338 @@
1++++
2+title = "3. Agent"
3+weight = 3
4+template = "doc.html"
5++++
6+
7+Now that we have our agent's types defined and have thought through its
8+behavior, we can write the `%journal` agent itself.
9+
10+## Imports
11+
12+```hoon
13+/- *journal
14+/+ default-agent, dbug, agentio
15+```
16+
17+We first import the `/sur/journal.hoon` file we previously created and expose
18+its structures. We import the standard `default-agent` and `dbug`, and also an additional library called `agentio`.
19+
20+Agentio contains a number of convenience functions to make common agent tasks
21+simpler. For example, rather than writing out the full `$card`s when sending
22+`%fact`s to subscribers, we can call `++fact` in `agentio` with the `cage` and
23+`path`s and it will compose them for us. There are many more functions in
24+`agentio` than we'll use here - you can have a look through the library in
25+[`/base/lib/agentio.hoon`](https://github.com/urbit/urbit/blob/master/pkg/base-dev/lib/agentio.hoon)
26+to see what else it can do.
27+
28+## State and type core
29+
30+```hoon
31+|%
32++$ versioned-state
33+ $% state-0
34+ ==
35++$ state-0 [%0 =journal =log]
36++$ card card:agent:gall
37+++ j-orm ((on id txt) gth)
38+++ log-orm ((on @ action) lth)
39+++ unique-time
40+ |= [=time =log]
41+ ^- @
42+ =/ unix-ms=@
43+ (unm:chrono:userlib time)
44+ |-
45+ ?. (has:log-orm log unix-ms)
46+ unix-ms
47+ $(time (add unix-ms 1))
48+--
49+```
50+
51+As we discussed in the previous section, our state will contain a `$journal`
52+structure containing all our journal entries, and a `$log` structure containing
53+the update log. These are both _ordered maps_, defined as `((mop id txt) gth)`
54+and `((mop @ action) lth)` respectively. We can therefore define our _versioned
55+state_ as `[%0 =journal =log]`, in the usual manner.
56+
57+We've define `$card` for convenience as usual, and we've also added three more
58+arms. The first two relate to our two ordered maps. If you'll recall, an
59+ordinary `map` is called with the `++by` door in the standard library, like so:
60+
61+```hoon
62+(~(get by foo) %bar)
63+```
64+
65+An ordered map uses the `++on` gate in `zuse.hoon` rather than `++by`, and its
66+invocation is slightly different. It must first be setup in a similar manner to
67+the `mop` type, by providing it the key/value molds and comparator gates. Once
68+that's done, its individual functions can be called with the `mop` and
69+arguments, like:
70+
71+```hoon
72+(get:((on @ud @ud) gth) foo %bar)
73+```
74+
75+This is quite a cumbersome expression to use every time we want to interact with
76+our `mop`. To make it easier, we can store the `((on @ud @ud) gth)` part in an
77+arm, and then when we need to use it we can just do `(get:arm-name foo %bar)`.
78+In this case, we've done one each of our ordered maps like so:
79+
80+```hoon
81+++ j-orm ((on id txt) gth)
82+++ log-orm ((on @ action) lth)
83+```
84+
85+The last arm in our state definition core is `++unique-time`. Since we'll use
86+`now.bowl` to derive the timestamp for updates, we run into an issue if multiple
87+pokes arrive in a single Arvo event. In that case, `now.bowl` would be the same
88+for each poke, so they'd be given the same key and override each other in the
89+`mop`. To avoid this, `++unique-time` is just a simple recursive function that
90+will increment the timestamp by one millisecond if the key already exists in the
91+`$log` `mop`, ensuring all updates get unique timestamps and there are no
92+collisions.
93+
94+## Agent core setup
95+
96+```hoon
97+%- agent:dbug
98+=| state-0
99+=* state -
100+^- agent:gall
101+|_ =bowl:gall
102++* this .
103+ def ~(. (default-agent this %|) bowl)
104+ io ~(. agentio bowl)
105+++ on-init on-init:def
106+++ on-save
107+ ^- vase
108+ !>(state)
109+::
110+++ on-load
111+ |= old-vase=vase
112+ ^- (quip card _this)
113+ `this(state !<(versioned-state old-vase))
114+::
115+```
116+
117+Here we setup our agent core and define the three lifecycle arms. Since we only
118+have a single state version at present, these are very simple functions. You'll
119+notice in our `+*` arm, along with the usual `this` and `def`, we've also setup
120+the `agentio` library we imported, giving it the bowl and an alias of `io`.
121+
122+## Pokes
123+
124+```hoon
125+++ on-poke
126+ |= [=mark =vase]
127+ ^- (quip card _this)
128+ |^
129+ ?> (team:title our.bowl src.bowl)
130+ ?. ?=(%journal-action mark) (on-poke:def mark vase)
131+ =/ now=@ (unique-time now.bowl log)
132+ =/ act !<(action vase)
133+ =. state (poke-action act)
134+ :_ this(log (put:log-orm log now act))
135+ ~[(fact:io journal-update+!>(`update`[now act]) ~[/updates])]
136+ ::
137+ ++ poke-action
138+ |= act=action
139+ ^- _state
140+ ?- -.act
141+ %add
142+ ?< (has:j-orm journal id.act)
143+ state(journal (put:j-orm journal id.act txt.act))
144+ ::
145+ %edit
146+ ?> (has:j-orm journal id.act)
147+ state(journal (put:j-orm journal id.act txt.act))
148+ ::
149+ %del
150+ ?> (has:j-orm journal id.act)
151+ state(journal +:(del:j-orm journal id.act))
152+ ==
153+ --
154+::
155+```
156+
157+Here we have our `++on-poke` arm, where we handle `$action`s. Since our
158+`%journal` agent is intended for local use only, we make sure only our ship or
159+our moons may perform actions with:
160+
161+```hoon
162+?> (team:title our.bowl src.bowl)
163+```
164+
165+We haven't yet written our mark files, but our mark for `$action`s will be
166+`%journal-action`, so we make sure that's what we've received and if not, call
167+`++on-poke:def` to crash with an error message. We make sure the the timestamps
168+are unique with our `++unique-time` function described earlier, and then we
169+extract the poke's vase to an `$action` structure and call `++poke-action` to
170+handle it. We've made `++on-poke` a door with a separate `++poke-action` arm to
171+make the logic a little simpler, but in principle we could have had it all
172+directly inside the main `++poke-action` gate, or even separated it out into a
173+helper core below.
174+
175+The logic in `++poke-action` is very simple, with three cases for each of the possible `$action`s:
176+
177+- `%add` - Add a new journal entry. We check it doesn't already exist with
178+ `++has:j-orm`, and then add it to our `$journal` with `++put:j-orm`.
179+
180+- `%edit` - Edit an existing journal entry. We make sure it _does_ exist with
181+ `++has:j-orm`, and then override the old entry with the new one using
182+ `++put:j-orm` again.
183+
184+- `%del` - Delete an existing journal entry. We make sure it exists again with
185+ `++has:j-orm`, and then use `++del:j-orm` to delete it from our `$journal`
186+ `mop`.
187+
188+Back in the main part of `++on-poke`, `++poke-action` updates the state with the
189+new `$journal`, then we proceed to:
190+
191+```hoon
192+:_ this(log (put:log-orm log now act))
193+~[(fact:io journal-update+!>(`update`[now act]) ~[/updates])]
194+```
195+
196+We add the timestamp to the action, converting it to a logged update. We add it
197+to the `$log` update log using `++put:log-orm`, and also send the logged update
198+out to subscribers on the `/updates` subscription path. We haven't written our
199+mark files yet, but `%journal-update` is the mark we'll use for `$update`s, so
200+we pack the `$update` in a vase and add the mark to make it a `$cage`. Notice
201+we're using the `++fact` function in `agentio` (which we aliased as `io`) rather
202+than manually composing the `%fact`.
203+
204+## Subscriptions
205+
206+```hoon
207+++ on-watch
208+ |= =path
209+ ^- (quip card _this)
210+ ?> (team:title our.bowl src.bowl)
211+ ?+ path (on-watch:def path)
212+ [%updates ~] `this
213+ ==
214+::
215+```
216+
217+Our subscription logic is extremely simple - we just have a single `/updates`
218+path, which the front-end or other local agents may subscribe to. All updates
219+get sent out on this path. We enforce local-only with the `team:title` check.
220+
221+We could have had our `++on-watch` arm send out some initial state to new
222+subscribers, but for our front-end we'll instead fetch the initial state
223+separately with a scry. This just makes it slightly easier if our front-end
224+needs to resubscribe at some point - it'll already have some state in that case
225+so we don't want it to get sent again.
226+
227+## Scry Endpoints
228+
229+```hoon
230+++ on-peek
231+ |= =path
232+ ^- (unit (unit cage))
233+ ?> (team:title our.bowl src.bowl)
234+ =/ now=@ (unm:chrono:userlib now.bowl)
235+ ?+ path (on-peek:def path)
236+ [%x %entries *]
237+ ?+ t.t.path (on-peek:def path)
238+ [%all ~]
239+ :^ ~ ~ %journal-update
240+ !> ^- update
241+ [now %jrnl (tap:j-orm journal)]
242+ ::
243+ [%before @ @ ~]
244+ =/ before=@ (rash i.t.t.t.path dem)
245+ =/ max=@ (rash i.t.t.t.t.path dem)
246+ :^ ~ ~ %journal-update
247+ !> ^- update
248+ [now %jrnl (tab:j-orm journal `before max)]
249+ ::
250+ [%between @ @ ~]
251+ =/ start=@
252+ =+ (rash i.t.t.t.path dem)
253+ ?:(=(0 -) - (sub - 1))
254+ =/ end=@ (add 1 (rash i.t.t.t.t.path dem))
255+ :^ ~ ~ %journal-update
256+ !> ^- update
257+ [now %jrnl (tap:j-orm (lot:j-orm journal `end `start))]
258+ ==
259+ ::
260+ [%x %updates *]
261+ ?+ t.t.path (on-peek:def path)
262+ [%all ~]
263+ :^ ~ ~ %journal-update
264+ !> ^- update
265+ [now %logs (tap:log-orm log)]
266+ ::
267+ [%since @ ~]
268+ =/ since=@ (rash i.t.t.t.path dem)
269+ :^ ~ ~ %journal-update
270+ !> ^- update
271+ [now %logs (tap:log-orm (lot:log-orm log `since ~))]
272+ ==
273+ ==
274+::
275+```
276+
277+Here we have our `++on-scry` arm. The scry endpoints we've defined are divided
278+into two parts: querying the update `$log` and retrieving entries from the
279+`$journal`. Each end-point is as follows:
280+
281+- `/x/entries/all` - Retrieve all entries in the `$journal`. Our front-end will
282+ use lazy-loading and only get a few at a time, so it won't use this. It's nice
283+ to have it though, in case other agents want to get that data.
284+
285+- `/x/entries/before/[before]/[max]` - Retrieve at most `[max]` entries older
286+ than the entry on `[before]` date. This is so our lazy-loading front-end can
287+ progressively load more as the user scrolls down the page. The Javascript
288+ front-end will format numbers without dot separators, so the path will look
289+ like `/x/entries/before/1648051573109/10`. We therefore have to use the
290+ [`++dem`](docs/hoon/reference/stdlib/4i#dem) parsing `rule` in a
291+ [`++rash`](/docs/hoon/reference/stdlib/4g#rash) parser to convert it to an
292+ ordinary atom. We then use the `++tap:log-orm` `mop` function to retrieve the
293+ requested range as a list and return it as an `$update` with a
294+ `%journal-update` mark.
295+
296+- `/x/entries/between/[start]/[end]` - Retrieve all journal entries between two
297+ dates. This is so our front-end can have a search function, where the user can
298+ enter a start and end date and get all the entries in between. The
299+ `++lot:j-orm` `mop` function returns the subset of a `mop` between the two
300+ given keys as a `mop`, and then we call `++tap:j-orm` to convert it to a list.
301+ The `++lot:j-orm function` excludes the start and end values, so we subtract 1
302+ from the start and add 1 to the end to make sure it includes the full range.
303+
304+- `/x/updates/all` - Retrieve the entire update `$log`. Our front-end won't use
305+ this but it might be useful for other agents, so we've included it here.
306+
307+- `/x/updates/since/[since]` - Retrieve all `$update`s that have happened since
308+ the specified timestamp, if any. This is so our front-end (or another agent)
309+ can resynchronize its state in the event its subscription is interrupted,
310+ without having to fetch everything from scratch again.
311+
312+We don't use any of the other agent arms, so the remainder have all been passed
313+to `default-agent` for handling:
314+
315+```hoon
316+++ on-leave on-leave:def
317+++ on-agent on-agent:def
318+++ on-arvo on-arvo:def
319+++ on-fail on-fail:def
320+--
321+```
322+
323+The full agent source can be viewed
324+[here](https://github.com/urbit/docs-examples/blob/main/journal-app/desk/app/journal.hoon).
325+
326+## Resources
327+
328+- [The Gall Guide](/docs/userspace/gall-guide/intro) - The Gall Guide covers all
329+ aspects of writing Gall agents in detail.
330+
331+- [Ordered map functions in
332+ `zuse.hoon`](https://github.com/urbit/urbit/blob/master/pkg/arvo/sys/zuse.hoon#L5284-L5688) -
333+ This section of `zuse.hoon` contains all the functions for working with
334+ `mop`s, and is well commented.
335+
336+- [`/lib/agentio.hoon`](https://github.com/urbit/urbit/blob/master/pkg/base-dev/lib/agentio.hoon) -
337+ The `agentio` library in the `%base` desk contains a large number of useful
338+ functions which making writing Gall agents easier.
content/docs/userspace/full-stack/4-json.mdnew file+357
@@ -0,0 +1,357 @@
1++++
2+title = "4. JSON"
3+weight = 4
4+template = "doc.html"
5++++
6+
7+Data sent between our agent and our front-end will all be encoded as JSON. In
8+this section, we'll briefly look at how JSON works in Urbit, and write a library
9+to convert our agent's structures to and from JSON for our front-end.
10+
11+JSON data comes into Eyre as a string, and Eyre parses it with the
12+[`++de-json:html`](/docs/hoon/reference/zuse/2e_2-3#de-jsonhtml) function in
13+[`zuse.hoon`](/docs/hoon/reference/zuse/table-of-contents). The
14+hoon type it's parsed to is `$json`, which is defined as:
15+
16+```hoon
17++$ json :: normal json value
18+ $@ ~ :: null
19+ $% [%a p=(list json)] :: array
20+ [%b p=?] :: boolean
21+ [%o p=(map @t json)] :: object
22+ [%n p=@ta] :: number
23+ [%s p=@t] :: string
24+ == ::
25+```
26+
27+Once Eyre has converted the raw JSON string to a `$json` structure, it will be
28+converted to the mark the web client specified and then delivered to the target
29+agent (unless the mark specified is already `%json`, in which case it will be
30+delivered directly). Outbound facts will go through the same process in
31+reverse - converted from the agent's native mark to `$json`, then encoded in a
32+string by Eyre using
33+[`++en-json:html`](<(/docs/hoon/reference/zuse/2e_2-3#en-jsonhtml)>) and delivered
34+to the web client. The basic flow for both inbound messages (pokes) and outbound
35+messages (facts and scry results) looks like this:
36+
37+![eyre mark flow diagram](https://media.urbit.org/docs/userspace/full-stack-guide/eyre-mark-flow-diagram.svg)
38+
39+The mark conversion will be done by the corresponding mark file in `/mar` on the
40+agent's desk. In our case it would be `/mar/journal/action.hoon` and
41+`/mar/journal/update.hoon` in the `%journal` desk for our `%journal-action` and
42+`%journal-update` marks, which are for the `$action` and `$update` structures we
43+defined previously.
44+
45+Mark conversion functions can be included directly in the mark file, or they can
46+be written in a separate library, then imported and called by the mark file. We
47+will do the latter in this case, so before we create the mark files themselves,
48+we'll write a library called `/lib/journal.hoon` with the conversion functions.
49+
50+## `$json` utilities
51+
52+[`zuse.hoon`](/docs/hoon/reference/zuse/table-of-contents) contains three main
53+cores for converting to and from `$json`:
54+
55+- [`++enjs:format`](/docs/hoon/reference/zuse/2d_1-5#enjsformat) - Functions to
56+ help encode data structures as `$json`.
57+- [`++dejs:format`](/docs/hoon/reference/zuse/2d_6#dejsformat) - Functions to
58+ decode `$json` to other data structures.
59+- [`++dejs-soft:format`](/docs/hoon/reference/zuse/2d_7#dejs-softformat) -
60+ Mostly the same as `++dejs:format` except the functions produce units which
61+ are null if decoding fails, rather than just crashing.
62+
63+### `++enjs:format`
64+
65+This contains ten functions for encoding `$json`. Most of them are for specific
66+hoon data types, such as `++tape:enjs:format`, `++ship:enjs:format`,
67+`++path:enjs:format`, etc. We'll just have a look at the two most general and
68+useful ones: `++frond:enjs:format` and `++pairs:enjs:format`.
69+
70+#### `++frond`
71+
72+This function is for forming a JSON object from a single key-value pair. For
73+example:
74+
75+```
76+> (frond:enjs:format 'foo' s+'bar')
77+[%o p={[p='foo' q=[%s p='bar']]}]
78+```
79+
80+When stringified by Eyre, this will look like:
81+
82+```json
83+{ "foo": "bar" }
84+```
85+
86+#### `++pairs`
87+
88+This is similar to `++frond` and also forms a JSON object, but it takes multiple
89+key-value pairs rather than just one:
90+
91+```
92+> (pairs:enjs:format ~[['foo' n+~.123] ['bar' s+'abc'] ['baz' b+&]])
93+[%o p={[p='bar' q=[%s p='abc']] [p='baz' q=[%b p=%.y]] [p='foo' q=[%n p=~.123]]}]
94+```
95+
96+When stringified by Eyre, this will look like:
97+
98+```json
99+{
100+ "foo": 123,
101+ "baz": true,
102+ "bar": "abc"
103+}
104+```
105+
106+Notice that we used a knot for the value of `foo` (`n+~.123`). Numbers in JSON
107+can be signed or unsigned and integers or floating point values. The `$json`
108+structure uses a knot so that you can decide whether a particular number should
109+be treated as `@ud`, `@sd`, `@rs`, etc.
110+
111+### `++dejs:format`
112+
113+This core contains many functions for decoding `$json`. We'll touch on some
114+useful families of `++dejs` functions in brief, but because there's so many, in
115+practice you'll need to look through the [`++dejs`
116+reference](/docs/hoon/reference/zuse/2d_6) to find the correct functions for
117+your use case.
118+
119+#### Number functions
120+
121+- `++ne` - decode a number to a `@rd`.
122+- `++ni` - decode a number to a `@ud`.
123+- `++no` - decode a number to a `@ta`.
124+- `++nu` - decode a hexadecimal string to a `@ux`.
125+
126+For example:
127+
128+```
129+> (ni:dejs:format n+'123')
130+123
131+```
132+
133+#### String functions
134+
135+- `++sa` - decode a string to a `tape`.
136+- `++sd` - decode a string containing a `@da` aura date value to a `@da`.
137+- `++se` - decode a string containing the specified aura to that aura.
138+- `++so` - decode a string to a `@t`.
139+- `++su` - decode a string by parsing it with the given [parsing
140+ rule](/docs/hoon/reference/stdlib/4f).
141+
142+#### Array functions
143+
144+`++ar`, `++as`, and `++at` decode a `$json` array to a `list`, `set`, and
145+n-tuple respectively. These gates take other `++dejs` functions as an argument,
146+producing a new gate that will then take the `$json` array. For example:
147+
148+```
149+> ((ar so):dejs:format a+[s+'foo' s+'bar' s+'baz' ~])
150+<|foo bar baz|>
151+```
152+
153+Notice that `++so` is given as the argument to `++ar`. `++so` is a `++dejs`
154+function that decodes a `$json` string to a `cord`. The gate resulting from `(ar so)` is then called with a `$json` array as its argument, and its product is a
155+`(list @t)` of the elements of the array.
156+
157+Many `++dejs` functions take other `++dejs` functions as their arguments. A
158+complex nested `$json` decoding function can be built up in this manner.
159+
160+#### Object functions
161+
162+- `++of` - decode an object containing a single key-value pair to a head-tagged
163+ cell.
164+- `++ot` - decode an object to a n-tuple.
165+- `++ou` - decode an object to an n-tuple, replacing optional missing values
166+ with a given value.
167+- `++oj` - decode an object of arrays to a `jug`.
168+- `++om` - decode an object to a `map`.
169+- `++op` - decode an object to a `map`, and also parse the object keys with a
170+ [parsing rule](/docs/hoon/reference/stdlib/4f).
171+
172+For example:
173+
174+```
175+> =js %- need %- de-json:html
176+ '''
177+ {
178+ "foo": "hello",
179+ "baz": true,
180+ "bar": 123
181+ }
182+ '''
183+
184+> %- (ot ~[foo+so bar+ni]):dejs:format js
185+['hello' 123]
186+```
187+
188+## Our types as JSON
189+
190+We need to decide how our `$action` and `$update` types will be represented as
191+JSON in order to write our conversion functions. There are many ways to do this,
192+but in this case we'll do it as follows:
193+
194+### Actions
195+
196+| JSON | Noun |
197+| ------------------------------------------------- | ---------------------------------------------- |
198+| `{"add":{"id":1648366311070,"txt":"some text"}}` | `[%add id=1.648.366.034.844 txt='some text']` |
199+| `{"edit":{"id":1648366311070,"txt":"some text"}}` | `[%edit id=1.648.366.034.844 txt='some text']` |
200+| `{"del":{"id":1648366311070}}` | `[%del id=1.648.366.034.844]` |
201+
202+### Updates
203+
204+| Noun | JSON |
205+| ----------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- |
206+| `[1.648.366.492.459 %add id=1.648.366.034.844 txt='some text']` | `{time:1648366481425,"add":{"id":1648366311070,"txt":"some text"}}` |
207+| `[1.648.366.492.459 %edit id=1.648.366.034.844 txt='some text']` | `{time:1648366481425,"edit":{"id":1648366311070,"txt":"some text"}}` |
208+| `[1.648.366.492.459 %del id=1.648.366.034.844]` | `{time:1648366481425,"del":{"id":1648366311070}}` |
209+| `[1.648.366.492.459 %jrnl ~[[id=1.648.366.034.844 txt='some text'] ...]` | `{time:1648366481425,"entries":[{"id":1648366311070,"txt":"some text"},...]}` |
210+| `[1.648.366.492.459 %logs ~[[1.648.366.492.459 %add id=1.648.366.034.844 txt='some text'] ...]` | `{time:1648366481425,"logs":[{time:1648366481425,"add":{id":1648366311070,"txt":"some text"}},...]}` |
211+
212+Now let's write our library of encoding/decoding functions.
213+
214+## `/lib/journal.hoon`
215+
216+```hoon
217+/- *journal
218+|%
219+```
220+
221+First, we'll import the `/sur/journal.hoon` structures we previously created.
222+Next, we'll create two arms in our core, `++dejs-action` and `++enjs-update`, to
223+handle incoming poke `$action`s and outgoing facts or scry result `$update`s.
224+
225+### `$json` to `$action`
226+
227+```hoon
228+++ dejs-action
229+ =, dejs:format
230+ |= jon=json
231+ ^- action
232+ %. jon
233+ %- of
234+ :~ [%add (ot ~[id+ni txt+so])]
235+ [%edit (ot ~[id+ni txt+so])]
236+ [%del (ot ~[id+ni])]
237+ ==
238+```
239+
240+The first thing we do is use the [`=,`
241+rune](/docs/hoon/reference/rune/tis#-tiscom) to expose the `++dejs:format`
242+namespace. This allows us to reference `ot`, `ni`, etc rather than having to
243+write `ot:dejs:format` every time. Note that you should be careful using `=,`
244+generally as the exposed wings can shadow previous wings if they have the same
245+name.
246+
247+We then create a gate that takes `$json` and returns a `$action` structure.
248+Since we'll only take one action at a time, we can use the `++of` function,
249+which takes a single key-value pair. `++of` takes a list of all possible `$json`
250+objects it will receive, tagged by key.
251+
252+For each key, we specify a function to handle its value. Ours will be objects,
253+so we use `++ot` and specify the pairs of the key and `+dejs` function to decode
254+it. We then cast the output to our `$action` structure.
255+
256+You'll notice the nesting of these `++dejs` functions approximately reflects the
257+nested structure of the `$json` it's decoding.
258+
259+### `$update` to `$json`
260+
261+```hoon
262+++ enjs-update
263+ =, enjs:format
264+ |= upd=update
265+ ^- json
266+ |^
267+ ?+ -.q.upd (logged upd)
268+ %jrnl
269+ %- pairs
270+ :~ ['time' (numb p.upd)]
271+ ['entries' a+(turn list.q.upd entry)]
272+ ==
273+ ::
274+ %logs
275+ %- pairs
276+ :~ ['time' (numb p.upd)]
277+ ['logs' a+(turn list.q.upd logged)]
278+ ==
279+ ==
280+ ++ entry
281+ |= ent=^entry
282+ ^- json
283+ %- pairs
284+ :~ ['id' (numb id.ent)]
285+ ['txt' s+txt.ent]
286+ ==
287+ ++ logged
288+ |= lgd=^logged
289+ ^- json
290+ ?- -.q.lgd
291+ %add
292+ %- pairs
293+ :~ ['time' (numb p.lgd)]
294+ :- 'add'
295+ %- pairs
296+ :~ ['id' (numb id.q.lgd)]
297+ ['txt' s+txt.q.lgd]
298+ == ==
299+ %edit
300+ %- pairs
301+ :~ ['time' (numb p.lgd)]
302+ :- 'edit'
303+ %- pairs
304+ :~ ['id' (numb id.q.lgd)]
305+ ['txt' s+txt.q.lgd]
306+ == ==
307+ %del
308+ %- pairs
309+ :~ ['time' (numb p.lgd)]
310+ :- 'del'
311+ (frond 'id' (numb id.q.lgd))
312+ ==
313+ ==
314+ --
315+--
316+```
317+
318+Our `$update` encoding function's a little more complex than our `$action`
319+decoding function, since our `$update` structure is more complex.
320+
321+Like the previous one, we use `=,` to expose the namespace of `++enjs:format`.
322+
323+Our gate takes an `$update` and returns a `$json` structure. We use `|^` so we
324+can separate out the encoding functions for individual entries (`++entry`) and
325+individual logged actions (`++logged`).
326+
327+We first test the head of the `$update`, and if it's `%jrnl` (a list of
328+entries), we `turn` over the entries and call `++entry` to encode each one. If
329+it's `%logs`, we do the same, but call `++logged` for each item in the list.
330+Otherwise, if it's just a single update, we encode it with `++logged`.
331+
332+We primarily use `++pairs` to form the object, though sometimes `++frond` if it
333+only contains a single key-value pair. We also use `++numb` to encode numerical
334+values.
335+
336+You'll notice more of our encoding function is done manually than our previous
337+decoding function. For example, we form arrays by tagging an ordinary `list`
338+with `%a`, and strings by tagging an ordinary `cord` with `%s`. This is typical
339+when you write `$json` encoding functions, and is the reason there are far fewer
340+`+enjs` functions than `+dejs` functions.
341+
342+## Resources
343+
344+- [The JSON Guide](/docs/hoon/guides/json-guide) - The stand-alone JSON guide
345+ covers JSON encoding/decoding in great detail.
346+- [The Zuse reference](/docs/hoon/reference/zuse/table-of-contents) - The
347+ `zuse.hoon` reference documents all JSON-related functions in detail.
348+
349+- [`++enjs:format` reference](/docs/hoon/reference/zuse/2d_1-5#enjsformat) -
350+ This section of the `zuse.hoon` documentation covers all JSON encoding
351+ functions.
352+
353+- [`++dejs:format` reference](/docs/hoon/reference/zuse/2d_6) - This section of
354+ the `zuse.hoon` documentation covers all JSON _decoding_ functions.
355+
356+- [Eyre overview](/docs/arvo/eyre/eyre) - This section of the Eyre vane
357+ documentation goes over the basic features of the Eyre vane.
content/docs/userspace/full-stack/5-marks.mdnew file+97
@@ -0,0 +1,97 @@
1++++
2+title = "5. Marks"
3+weight = 5
4+template = "doc.html"
5++++
6+
7+In this section we'll write the mark files for our agent. We'll need two marks,
8+one for poke `$action`s and one for subscription updates and scry results, both
9+of which are `$update`s. Our `$action` mark will be called `%journal-action` and
10+our `$update` mark will be called `%journal-update`. These will be located at
11+`/mar/journal/action.hoon` and `/mar/journal/update.hoon`.
12+
13+Note that a mark called `%foo-bar` will first be looked for in
14+`/mar/foo-bar.hoon`, and if it's not there it will be looked for in
15+`/mar/foo/bar.hoon`. That's why we can have a single name like `%journal-action`
16+but have it in `/mar/journal/action.hoon`
17+
18+## `%journal-action`
19+
20+```hoon
21+/- *journal
22+/+ *journal
23+|_ act=action
24+++ grow
25+ |%
26+ ++ noun act
27+ --
28+++ grab
29+ |%
30+ ++ noun action
31+ ++ json dejs-action
32+ --
33+++ grad %noun
34+--
35+```
36+
37+First we import our `/sur/journal.hoon` structure file and also our
38+`/lib/journal.hoon` library (containing our `$json` conversion functions). The
39+sample of our mark door is just our `$action` structure. The `++grow` arm of a
40+mark core, if you recall, contains methods for converting _from_ our mark _to_
41+another mark. Actions only ever come inwards in pokes, so we don't need to worry
42+about converting an `$action` _to_ `$json`. The `++grow` arm can therefore just
43+handle the generic `%noun` case, simply returning our mark door's sample without
44+doing anything.
45+
46+`++grab`, conversely, defines methods for converting _to_ our mark _from_
47+another mark. Since `$action`s will come in from the front-end as `$json`, we
48+need to be able to convert `$json` data to our `$action` structure. Our
49+`/lib/journal.hoon` library contains the `++dejs-action` function for performing
50+this conversion, so we can just specify that function for the `%json` case.
51+We'll also define a standard `%noun` method, which will just "clam" (or "mold")
52+the incoming noun with the `$action` mold. Clamming/molding coerces a noun to a
53+type and is done by calling a mold as a function.
54+
55+Lastly, `++grad` defines revision control methods, but can be delegated to
56+another mark. Since this mark will never be used for actually storing files in
57+Clay, we can just delegate it to the generic `%noun` mark rather than writing a
58+proper set of `++grad` methods.
59+
60+## `%journal-update`
61+
62+```hoon
63+/- *journal
64+/+ *journal
65+|_ upd=update
66+++ grow
67+ |%
68+ ++ noun upd
69+ ++ json (enjs-update upd)
70+ --
71+++ grab
72+ |%
73+ ++ noun update
74+ --
75+++ grad %noun
76+--
77+```
78+
79+Next we have our `%journal-update` mark file. The sample of our mark door is our
80+`$update` structure. Our `$update`s are always outbound, never inbound, so we
81+only need to define a method for converting our `$update` structure to `$json`
82+in the `++grow` arm, and not the opposite direction in `++grad`. Our
83+`/lib/journal.hoon` library contains the `++enjs-update` function for performing
84+this conversion, so we can call it with the sample `$update` as its argument. We
85+can add `%noun` conversion methods and delegate revision control to the `%noun`
86+mark in the same manner as our `%journal-action` mark above.
87+
88+## Resources
89+
90+- [The Marks section of the Clay documentation](/docs/arvo/clay/marks/marks) -
91+ This section of the Clay vane documentation covers mark files comprehensively.
92+- [The mark file section of the Gall
93+ Guide](/docs/userspace/gall-guide/7-sur-and-marks#mark-files) - This part of
94+ the Gall Guide goes through the basics of mark files.
95+
96+- [The JSON Guide](/docs/hoon/guides/json-guide) - This also covers writing mark
97+ files to convert to/from JSON.
content/docs/userspace/full-stack/6-eyre.mdnew file+79
@@ -0,0 +1,79 @@
1++++
2+title = "6. Eyre"
3+weight = 6
4+template = "doc.html"
5++++
6+
7+Now that we have our structure file, agent, `$json` conversion library and mark
8+file, our back-end is complete. Before we start writing our front-end, though,
9+we should give a brief overview of how Eyre works.
10+
11+[Eyre](/docs/arvo/eyre/eyre) is the HTTP server [vane](/docs/glossary/vane) of
12+Arvo. Eyre has a handful of different subsystems, but the main two are the
13+channel system and the scry interface. These two are what we'll focus on here.
14+
15+In order to use the channel system or perform scries, a web client must have
16+authenticated with the ship's web login code (e.g.
17+`lidlut-tabwed-pillex-ridrup`) and obtained a session cookie. Our front-end will
18+be served directly from the ship by the `%docket` agent, so we can assume a
19+session cookie was already obtained when the user logged into landscape, and
20+skip over authentication.
21+
22+## Channels
23+
24+Eyre's channel system is the main way to interact with agents from a web client.
25+It provides a JSON interface to the ordinary poke and subscription system for
26+Gall agents.
27+
28+First, a unique channel ID is generated by the web client (`@urbit/http-api`
29+uses the current Unix time concatenated with a random hex string). The client
30+then sends a poke or subscription request for the channel, and Eyre
31+automatically opens a new channel with that ID. Once open, the client can then
32+connect to the channel and receive any events such as poke acks, watch acks,
33+facts from subscriptions, etc.
34+
35+The new channel is an SSE ([Server Sent
36+Event](https://html.spec.whatwg.org/#server-sent-events)) stream, and can be
37+handled by an `EventSource` object in Javascript. The `@urbit/http-api` library
38+we'll use abstracts this for us, so we won't need to deal with an `EventSource`
39+object directly. The channel can handle multiple concurrent subscriptions to
40+different agent subscription paths, and different agents can be poked through
41+the one channel. This means a client only needs to open a single channel for all
42+of its interactions with the ship. Each subscription is given a different ID, so
43+they can be individually unsubscribed later.
44+
45+A channel will timeout after 12 hours of inactivity, and the timeout is reset
46+every time Eyre receives a message of any kind from the client. Additionally,
47+each subscription on the channel may only accumulate 50 unacknowledged facts
48+before it's considered "clogged", in which case the individual clogged
49+subscription will be closed by Eyre after a short delay. All events of any kind
50+which Eyre sends out on the channel must be ack'd by the client. Ack'ing one
51+event will also ack all previous events too. The `@urbit/http-api` library we'll
52+use automatically acks events for us, so we don't need to worry about clogged
53+subscriptions or manually ack'ing events.
54+
55+Eyre expects a particular JSON object structure for each of these different
56+requests, but the `@urbit/http-api` library we'll use includes functions to send
57+pokes, subscription requests, etc, so we won't need to manually construct the
58+JSON objects in our front-end.
59+
60+## Scries
61+
62+Eyre's scry interface is separate to the channel system. Scries are performed by
63+a simple GET request to a path with a format of `/~/scry/{agent}{path}.{mark}`.
64+If successful, the HTTP response will contain the result with the mark
65+specified. If unsuccessful, an HTTP error will be thrown in response.
66+
67+The `@urbit/http-api` library we'll use includes a function for performing
68+scries, so we'll not need to manually send GET requests to the ship.
69+
70+## Resources
71+
72+- [The Eyre vane documentation](/docs/arvo/eyre/eyre) - This section of the vane
73+ docs covers all aspects of Eyre.
74+- [Eyre External API Reference](/docs/arvo/eyre/external-api-ref) - This section
75+ of the Eyre documentation contains reference material for Eyre's external API.
76+
77+- [The Eyre Guide](/docs/arvo/eyre/guide) - This section of the Eyre
78+ documentation walks through using Eyre's external API at a low level (using
79+ `curl`).
content/docs/userspace/full-stack/7-react-setup.mdnew file+214
@@ -0,0 +1,214 @@
1++++
2+title = "7. React app setup"
3+weight = 7
4+template = "doc.html"
5++++
6+
7+Now that we have a basic idea of how Eyre works, we can begin working on our
8+React app front-end.
9+
10+## Create React app
11+
12+Node.js must be installed, and can be downloaded from their
13+[website](https://nodejs.org/en/download). With that installed, we'll have the
14+`npm` package manager available. The first thing we'll do is globally install
15+the `create-react-app` package with the following command:
16+
17+```sh
18+npm install -g create-react-app
19+```
20+
21+Once installed, we can use it to create a new `journal-ui` directory and setup a
22+new React app in it with the following command:
23+
24+```sh
25+create-react-app journal-ui
26+```
27+
28+We can then open our new directory:
29+
30+```sh
31+cd journal-ui
32+```
33+
34+Its contents should look something like this:
35+
36+```
37+journal-ui
38+├── node_modules
39+├── package.json
40+├── package-lock.json
41+├── public
42+├── README.md
43+└── src
44+```
45+
46+## Install `http-api`
47+
48+Inside our React app directory, let's install the `@urbit/http-api` NPM package:
49+
50+```sh
51+npm i @urbit/http-api
52+```
53+
54+We also install a handful of other packages for the UI components (`bootstrap react-bootstrap react-textarea-autosize date-fns react-bottom-scroll-listener react-day-picker`), but that's not important to our purposes here.
55+
56+## Additional tweaks
57+
58+Our front-end will be served directly from the ship by the `%docket` app, where
59+a user will open it by clicking on its homescreen tile. Docket serves such
60+front-ends with a base URL path of `/apps/[desk]/`, so in our case it will be
61+`/apps/journal`. In order for our app to be built with correct resource paths,
62+we must add the following line to `package.json`:
63+
64+```json
65+"homepage": "/apps/journal/",
66+```
67+
68+Our app also needs to know the name of the ship it's being served from in order
69+to talk with it. The `%docket` agent serves a small file for this purpose at
70+`[host]/session.js`. This file is very simple and just contains:
71+
72+```js
73+window.ship = "sampel-palnet";
74+```
75+
76+`sampel-palnet` will of course be replaced by the actual name of the ship. We
77+include this script by adding the following line to the `&lt;head>` section of
78+`public/index.html`:
79+
80+```
81+<script src="/session.js"></script>
82+```
83+
84+## Basic API setup
85+
86+With everything now setup, we can begin work on the app itself. In this case
87+we'll just edit the existing `App.js` file in the `/src` directory. The first thing is to import the `Urbit` class from `@urbit/http-api`:
88+
89+```js
90+import Urbit from "@urbit/http-api";
91+```
92+
93+We also need to import a few other things, mostly relating to UI components (but
94+these aren't important for our purposes here):
95+
96+```js
97+import React, { Component } from "react";
98+import "bootstrap/dist/css/bootstrap.min.css";
99+import "react-day-picker/lib/style.css";
100+import TextareaAutosize from "react-textarea-autosize";
101+import Button from "react-bootstrap/Button";
102+import Card from "react-bootstrap/Card";
103+import Stack from "react-bootstrap/Stack";
104+import Tab from "react-bootstrap/Tab";
105+import Tabs from "react-bootstrap/Tabs";
106+import ToastContainer from "react-bootstrap/ToastContainer";
107+import Toast from "react-bootstrap/Toast";
108+import Spinner from "react-bootstrap/Spinner";
109+import CloseButton from "react-bootstrap/CloseButton";
110+import Modal from "react-bootstrap/Modal";
111+import DayPickerInput from "react-day-picker/DayPickerInput";
112+import endOfDay from "date-fns/endOfDay";
113+import startOfDay from "date-fns/startOfDay";
114+import { BottomScrollListener } from "react-bottom-scroll-listener";
115+```
116+
117+Inside the existing `App` class:
118+
119+```js
120+class App extends Component {
121+```
122+
123+...we'll clear out the existing demo code and start adding ours. The first thing
124+is to define our app's state. We'll look at most of the state entries in the
125+next section. For now, we'll just consider `status`.
126+
127+```js
128+state = {
129+ // .....
130+ status: null,
131+ // .....
132+};
133+```
134+
135+Next, we'll setup the `Urbit` API object in `componentDidMount`. We could do
136+this outside the `App` class since we're adding it to `window`, but we'll do it
137+this way so it's all in one place:
138+
139+```js
140+componentDidMount() {
141+ window.urbit = new Urbit("");
142+ window.urbit.ship = window.ship;
143+ window.urbit.onOpen = () => this.setState({status: "con"});
144+ window.urbit.onRetry = () => this.setState({status: "try"});
145+ window.urbit.onError = (err) => this.setState({status: "err"});
146+ this.init();
147+};
148+```
149+
150+The first thing we do is create a new instance of the `Urbit` class we imported
151+from `@urbit/http-api`, and save it to `window.urbit`. The `Urbit` class
152+constructor takes three arguments: `url`, `desk` and `code`, of which only `url`
153+is mandatory.
154+
155+- `url` is the URL of the ship we want to talk to. Since our React app will be
156+ served by the ship, we can just leave it as an empty `""` string and let
157+ `Urbit` use root-relative paths.
158+- `desk` is only necessary if we want to run threads through Eyre, and since
159+ we're not going to do that, we can exclude it.
160+- `code` is the web login code for authentication, but since the user will
161+ already have logged in, we can also exclude that.
162+
163+Therefore, we call the class contructor with just the empty `url` string:
164+
165+```js
166+window.urbit = new Urbit("");
167+```
168+
169+Next, we need to set the ship name in our `Urbit` instance. Eyre requires the
170+ship name be specified in all requests, so if we don't set it, Eyre will reject
171+all the messages we send. We previously included `session.js` which sets
172+`window.ship` to the ship name, so we just set `window.urbit.ship` as that:
173+
174+```js
175+window.urbit.ship = window.ship;
176+```
177+
178+Next, we set three callbacks: `onOpen`, `onRetry`, and `onError`. These
179+callbacks are fired when the state of our channel connection changes:
180+
181+- `onOpen` is called when a connection is established.
182+- `onRetry` is called when a channel connection has been interrupted (such as by
183+ network issues) and the `Urbit` object is trying to reconnect. Reconnection
184+ will be attempted up to three times: immediately, after 750ms, and after
185+ 3000ms.
186+- `onError` is called with an `Error` message once all retries have failed, or
187+ otherwise when a fatal error occurs.
188+
189+We'll look at how we handle these cases in the next section. For now, we'll just
190+set the `status` entry in the state to either `"con"`, `"try"`, or `"err"` as
191+the case may be. Note that it's not mandatory to set these callbacks, but
192+leaving connection problems unhandled is usually a bad idea.
193+
194+The last thing we do is call:
195+
196+```js
197+this.init();
198+```
199+
200+This function will fetch initial entries and subscribe for updates. We'll look
201+at it in the next section.
202+
203+## Resources
204+
205+- [HTTP API Guide](/docs/userspace/http-api-guide) - Reference documentation for
206+ `@urbit/http-api`.
207+
208+- [React app source
209+ code](https://github.com/urbit/docs-examples/tree/main/journal-app/ui) - The
210+ source code for the Journal app UI.
211+
212+- [`@urbit/http-api` source
213+ code](https://github.com/urbit/urbit/tree/master/pkg/npm/http-api) - The
214+ source code for the `@urbit/http-api` NPM package.
content/docs/userspace/full-stack/8-app-logic.mdnew file+406
@@ -0,0 +1,406 @@
1++++
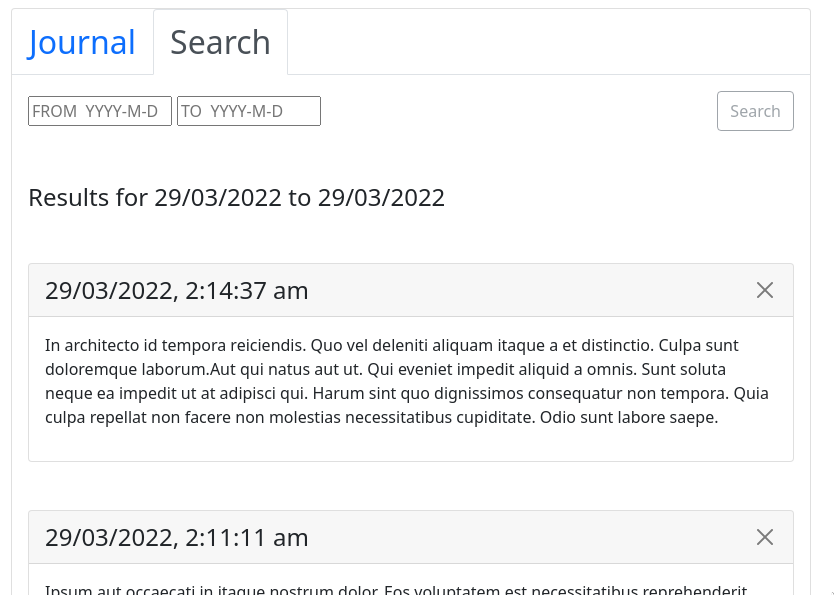
2+title = "8. React app logic"
3+weight = 8
4+template = "doc.html"
5++++
6+
7+With the basic things setup, we can now go over the logic of our app. We'll just
8+focus on functions that are related to ship communications using the `Urbit`
9+object we previously setup, and ignore UI components and other helper functions.
10+
11+## State
12+
13+In the previous section we just mentioned the connection `status` field of our
14+state. Here's the full state of our App:
15+
16+```js
17+state = {
18+ entries: [], // list of journal entries for display
19+ drafts: {}, // edits which haven't been submitted yet
20+ newDraft: {}, // new entry which hasn't been submitted yet
21+ results: [], // search results
22+ searchStart: null, // search query start date
23+ searchEnd: null, // search query end date
24+ resultStart: null, // search results start date
25+ resultEnd: null, // search results end date
26+ searchTime: null, // time of last search
27+ latestUpdate: null, // most recent update we've received
28+ entryToDelete: null, // deletion target for confirmation modal
29+ status: null, // connection status (con, try, err)
30+ errorCount: 0, // number of errors so far
31+ errors: new Map(), // list of error messages for display
32+};
33+```
34+
35+We'll see how these are used subsequently.
36+
37+## Initialize
38+
39+The first thing our app does is call `init()`:
40+
41+```js
42+init = () => {
43+ this.getEntries().then(
44+ (result) => {
45+ this.handleUpdate(result);
46+ this.setState({ latestUpdate: result.time });
47+ this.subscribe();
48+ },
49+ (err) => {
50+ this.setErrorMsg("Connection failed");
51+ this.setState({ status: "err" });
52+ }
53+ );
54+};
55+```
56+
57+This function just calls `getEntries()` to retrieve the initial list of journal
58+entries then, if that succeeded, it calls `subscribe()` to subscribe for new
59+updates. If the initial entry retrieval failed, we set the connection `status`
60+and save an error message in the `errors` map. We'll look at what we do with
61+errors later.
62+
63+## Getting entries
64+
65+![entries screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/entries.png)
66+
67+The `getEntries` function scries our `%journal` agent for up to 10 entries
68+before the oldest we currently have. We call this initially, and then each time
69+the user scrolls to the bottom of the list.
70+
71+```js
72+getEntries = async () => {
73+ const { entries: e } = this.state;
74+ const before = e.length === 0 ? Date.now() : e[e.length - 1].id;
75+ const max = 10;
76+ const path = `/entries/before/${before}/${max}`;
77+ return window.urbit.scry({
78+ app: "journal",
79+ path: path,
80+ });
81+};
82+```
83+
84+The scry is done with the `Urbit.scry` method. This function takes two arguments
85+in an object:
86+
87+- `app` - the agent to scry.
88+- `path` - the scry path. Note the `care` is not included - all scries through
89+ Eyre are `%x` scries.
90+
91+The `Urbit.scry` method only allows JSON results, but note that scries done via
92+direct GET requests allow other marks too.
93+
94+The `Urbit.scry` method returns a Promise which will contain an HTTP error
95+message if the scry failed. We handle it with a `.then` expression back in the
96+function that called it, either [`init()`](#initialize) or `moreEntries()`. If
97+the Promise is successfuly, the results are passed to the
98+[`handleUpdate`](#updates) function which appends the new entries to the
99+existing ones in state.
100+
101+## Subscription
102+
103+A subscription to the `/updates` path of our `%journal` agent is opened with our
104+`subscribe()` function:
105+
106+```js
107+subscribe = () => {
108+ try {
109+ window.urbit.subscribe({
110+ app: "journal",
111+ path: "/updates",
112+ event: this.handleUpdate,
113+ err: () => this.setErrorMsg("Subscription rejected"),
114+ quit: () => this.setErrorMsg("Kicked from subscription"),
115+ });
116+ } catch {
117+ this.setErrorMsg("Subscription failed");
118+ }
119+};
120+```
121+
122+We use the `Urbit.subscribe` method for this, which takes five arguments in an
123+object:
124+
125+- `app` - the target agent.
126+- `path` - the `%watch` path we're subscribing to.
127+- `event` - a function to handle each fact the agent sends out. We call our
128+ `handleUpdate` function, which we'll describe below.
129+- `err` - a function to call if the subscription request is rejected (nacked).
130+ We just display an error in this case.
131+- `quit` - a function to call if we get kicked from the subscription. We also
132+ just display an error in this case.
133+
134+Note that the `Urbit.subscribe` method returns a subscription ID number. Since
135+we only have one subscription in our app which we never close, we don't bother
136+to record it. If your app has multiple subscriptions to manage, you may wish to
137+keep track of these IDs in your app's state.
138+
139+## Updates
140+
141+This `handleUpdate` function handles all updates we receive. It's called
142+whenever an event comes in for our subscription, and it's also called with the
143+results of [`getEntries`](#getting-entries) and [`getUpdates`](#error-handling)
144+(described later).
145+
146+It's a bit complex, but basically it just checks whether the JSON object is
147+`add`, `edit`, `delete`, or `entries`, and then updates the state appropriately.
148+The object it's receiving is just the `$update` structure converted to JSON by
149+the mark conversion functions we wrote previously.
150+
151+```js
152+handleUpdate = (upd) => {
153+ const { entries, drafts, results, latestUpdate } = this.state;
154+ if (upd.time !== latestUpdate) {
155+ if ("entries" in upd) {
156+ this.setState({ entries: entries.concat(upd.entries) });
157+ } else if ("add" in upd) {
158+ const { time, add } = upd;
159+ const eInd = this.spot(add.id, entries);
160+ const rInd = this.spot(add.id, results);
161+ const toE =
162+ entries.length === 0 || add.id > entries[entries.length - 1].id;
163+ const toR = this.inSearch(add.id, time);
164+ toE && entries.splice(eInd, 0, add);
165+ toR && results.splice(rInd, 0, add);
166+ this.setState({
167+ ...(toE && { entries: entries }),
168+ ...(toR && { results: results }),
169+ latestUpdate: time,
170+ });
171+ } else if ("edit" in upd) {
172+ const { time, edit } = upd;
173+ const eInd = entries.findIndex((e) => e.id === edit.id);
174+ const rInd = results.findIndex((e) => e.id === edit.id);
175+ const toE = eInd !== -1;
176+ const toR = rInd !== -1 && this.inSearch(edit.id, time);
177+ if (toE) entries[eInd] = edit;
178+ if (toR) results[rInd] = edit;
179+ (toE || toR) && delete drafts[edit.id];
180+ this.setState({
181+ ...(toE && { entries: entries }),
182+ ...(toR && { results: results }),
183+ ...((toE || toR) && { drafts: drafts }),
184+ latestUpdate: time,
185+ });
186+ } else if ("del" in upd) {
187+ const { time, del } = upd;
188+ const eInd = entries.findIndex((e) => e.id === del.id);
189+ const rInd = results.findIndex((e) => e.id === del.id);
190+ const toE = eInd !== -1;
191+ const toR = this.inSearch(del.id, time) && rInd !== -1;
192+ toE && entries.splice(eInd, 1);
193+ toR && results.splice(rInd, 1);
194+ (toE || toR) && delete drafts[del.id];
195+ this.setState({
196+ ...(toE && { entries: entries }),
197+ ...(toR && { results: results }),
198+ ...((toE || toR) && { drafts: drafts }),
199+ latestUpdate: time,
200+ });
201+ }
202+ }
203+};
204+```
205+
206+## Add, edit, delete
207+
208+![add screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/add.png)
209+
210+When a user writes a new journal entry and hits submit, the `submitNew` function
211+is called. It uses the `Urbit.poke` method to poke our `%journal` agent.
212+
213+```js
214+submitNew = (id, txt) => {
215+ window.urbit.poke({
216+ app: "journal",
217+ mark: "journal-action",
218+ json: { add: { id: id, txt: txt } },
219+ onSuccess: () => this.setState({ newDraft: {} }),
220+ onError: () => this.setErrorMsg("New entry rejected"),
221+ });
222+};
223+```
224+
225+The `Urbit.poke` method takes five arguments:
226+
227+- `app` is the agent to poke.
228+- `mark` is the mark of the data we're sending. We specify `"journal-action"`,
229+ so Eyre will use the `/mar/journal/action.hoon` mark we created to convert it
230+ to a `$action` structure with a `%journal-action` mark before it's delivered
231+ to our agent.
232+- `json` is the actual data we're poking our agent with. In this case it's the
233+ JSON form of the `%add` `$action`.
234+- `onSuccess` is a callback that fires if we get a positive ack in response. In
235+ this case we just clear the draft.
236+- `onError` is a callback that fires if we get a negative ack (nack) in
237+ response, meaning the poke failed. In this case we just set an error message
238+ to be displayed.
239+
240+`onSuccess` and `onError` are optional, but it's usually desirable to handle
241+these cases.
242+
243+The `delete` and `submitEdit` functions are similar to `submitNew`, but for the
244+`%del` and `%edit` actions rather than `%add`:
245+
246+![edit screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/edit.png)
247+
248+```js
249+submitEdit = (id, txt) => {
250+ if (txt !== null) {
251+ window.urbit.poke({
252+ app: "journal",
253+ mark: "journal-action",
254+ json: { edit: { id: id, txt: txt } },
255+ onError: () => this.setErrorMsg("Edit rejected"),
256+ });
257+ } else this.cancelEdit(id);
258+};
259+```
260+
261+![delete screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/delete.png)
262+
263+```js
264+delete = (id) => {
265+ window.urbit.poke({
266+ app: "journal",
267+ mark: "journal-action",
268+ json: {"del": {"id": id}},
269+ onError: ()=>this.setErrorMsg("Deletion rejected")
270+ })
271+ this.setState({rmModalShow: false, entryToDelete: null})
272+};
273+```
274+
275+Note that whether we're adding, editing or deleting entries, we update our state
276+when we receive the update back on the `/updates` subscription, not when we poke
277+our agent.
278+
279+## Search
280+
281+![search screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/search.png)
282+
283+When searching for entries between two dates, the `getSearch` function is
284+called, which uses the `Urbit.scry` method to scry for the results in a similar
285+fashion to [`getEntries`](#getting-entries), but using the
286+`/x/entries/between/[start]/[end]` endpoint.
287+
288+```js
289+getSearch = async () => {
290+ const { searchStart: ss, searchEnd: se, latestUpdate: lu } = this.state;
291+ if (lu !== null && ss !== null && se !== null) {
292+ let start = ss.getTime();
293+ let end = se.getTime();
294+ if (start < 0) start = 0;
295+ if (end < 0) end = 0;
296+ const path = `/entries/between/${start}/${end}`;
297+ window.urbit
298+ .scry({
299+ app: "journal",
300+ path: path,
301+ })
302+ .then(
303+ (result) => {
304+ this.setState({
305+ searchTime: result.time,
306+ searchStart: null,
307+ searchEnd: null,
308+ resultStart: ss,
309+ resultEnd: se,
310+ results: result.entries,
311+ });
312+ },
313+ (err) => {
314+ this.setErrorMsg("Search failed");
315+ }
316+ );
317+ } else {
318+ lu !== null && this.setErrorMsg("Searh failed");
319+ }
320+};
321+```
322+
323+## Error handling
324+
325+When the channel connection is interrupted, the `Urbit` object will begin trying to reconnect. On each attempt, it sets the connection `status` to `"try"`, as we specified for the `onRetry` callback. When this is set, a "reconnecting" message is displayed at the bottom of the screen:
326+
327+![reconnecting screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/reconnecting.png)
328+
329+If all three reconnection attempts fail, the `onError` callback is fired and we replace the "reconnecting" message with a "reconnect" button:
330+
331+![reconnect screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/reconnect.png)
332+
333+When clicked, the following function is called:
334+
335+```js
336+reconnect = () => {
337+ window.urbit.reset();
338+ const latest = this.state.latestUpdate;
339+ if (latest === null) {
340+ this.init();
341+ } else {
342+ this.getUpdates().then(
343+ (result) => {
344+ result.logs.map((e) => this.handleUpdate(e));
345+ this.subscribe();
346+ },
347+ (err) => {
348+ this.setErrorMsg("Connection failed");
349+ this.setState({ status: "err" });
350+ }
351+ );
352+ }
353+};
354+```
355+
356+Our `reconnect()` function first calls the `Urbit.reset` method. This closes the
357+channel connection, wipes event counts and subscriptions, and generates a new
358+channel ID. We could have tried reconnecting without resetting the connection,
359+but we don't know whether the channel still exists. We could time how long the
360+connection has been down and estimate whether it still exists, but it's easier
361+to just start fresh in this case.
362+
363+Since we've reset the channel, we don't know if we've missed any updates. Rather
364+than having to refresh our whole state, we can use the `getUpdates()` function
365+to get any missing update:
366+
367+```js
368+getUpdates = async () => {
369+ const { latestUpdate: latest } = this.state;
370+ const since = latest === null ? Date.now() : latest;
371+ const path = `/updates/since/${since}`;
372+ return window.urbit.scry({
373+ app: "journal",
374+ path: path,
375+ });
376+};
377+```
378+
379+This function uses the `Urbit.scry` method to scry the
380+`/x/updates/since/[since]` path, querying the update `$log` for entries more
381+recent than `latestUpdate`, which is always set to the last logged action we
382+received. The `getUpdates` function returns a Promise to the `reconnect`
383+function above which called it. The `reconnect` function handles it in a `.then`
384+expression, where the success case passes each update retrieved to the
385+[`handleUpdate`](#updates) function, updating our state.
386+
387+Lastly, as well as handling channel connection errors, we also handle errors
388+such as poke nacks or failed scries by printing error messages added to the
389+`error` map by the `setErrorMsg` function. You could of course handle nacks,
390+kicks, scry failures, etc differently than just printing an error, it depends on
391+the needs of your app.
392+
393+![search failed screenshot](https://media.urbit.org/docs/userspace/full-stack-guide/search-failed.png)
394+
395+## Resources
396+
397+- [HTTP API Guide](/docs/userspace/http-api-guide) - Reference documentation for
398+ `@urbit/http-api`.
399+
400+- [React app source
401+ code](https://github.com/urbit/docs-examples/tree/main/journal-app/ui) - The
402+ source code for the Journal app UI.
403+
404+- [`@urbit/http-api` source
405+ code](https://github.com/urbit/urbit/tree/master/pkg/npm/http-api) - The
406+ source code for the `@urbit/http-api` NPM package.
content/docs/userspace/full-stack/9-desk.mdnew file+226
@@ -0,0 +1,226 @@
1++++
2+title = "9. Desk and glob"
3+weight = 9
4+template = "doc.html"
5++++
6+
7+With our React app now complete, we can put together the final desk and publish
8+it.
9+
10+## Config files
11+
12+So far we've written the following files for the back-end:
13+
14+```
15+ourfiles
16+├── app
17+│ └── journal.hoon
18+├── lib
19+│ └── journal.hoon
20+├── mar
21+│ └── journal
22+│ ├── action.hoon
23+│ └── update.hoon
24+└── sur
25+ └── journal.hoon
26+```
27+
28+There's a handful of extra files we need in the root of our desk:
29+
30+- `desk.bill` - the list of agents that should be started when our app is
31+ installed.
32+- `sys.kelvin` - the kernel version our app is compatible with.
33+- `desk.docket-0` - configuration of our app tile, front-end glob and other
34+ metadata.
35+
36+We only have one agent to start, so `desk.bill` is very simple:
37+
38+```
39+:~ %journal
40+==
41+```
42+
43+Likewise, `sys.kelvin` just contains:
44+
45+```
46+[%zuse 419]
47+```
48+
49+The `desk.docket-0` file is slightly more complicated:
50+
51+```
52+:~
53+ title+'Journal'
54+ info+'Dear diary...'
55+ color+0xd9.b06d
56+ version+[0 1 0]
57+ website+'https://urbit.org'
58+ license+'MIT'
59+ base+'journal'
60+ glob-ames+[~zod 0v0]
61+==
62+```
63+
64+The fields are as follows:
65+
66+- `title` is the name of the app - this will be displayed on the tile and when
67+ people search for the app to install it.
68+- `info` is a brief description of the app.
69+- `color` - the RGB hex color of the tile.
70+- `version` - the version number of the app. The fields represent major, minor
71+ and patch version.
72+- `website` - a link to a website for the app. This would often be its Github repo.
73+- `license` - the license of for the app.
74+- `base` - the desk name of the app.
75+- `glob-ames` - the ship to retrieve the front-end files from, and the hash of
76+ those files. We've put `~zod` here but this would be the actual ship
77+ distributing the app when it's live on the network. The hash is `0v0`
78+ initially, but once we upload the front-end files it will be updated to the
79+ hash of those files automatically. Note that it's also possible to distribute
80+ front-end files from a separate web server. In that case, you'd use
81+ `glob-http` rather than `glob-ames`. The [Glob section of the distribution
82+ guide](/docs/userspace/dist/glob) covers this alternative approach in more
83+ detail.
84+
85+Our files should now look like this:
86+
87+```
88+ourfiles
89+├── app
90+│ └── journal.hoon
91+├── desk.bill
92+├── desk.docket-0
93+├── lib
94+│ └── journal.hoon
95+├── mar
96+│ └── journal
97+│ ├── action.hoon
98+│ └── update.hoon
99+├── sur
100+│ └── journal.hoon
101+└── sys.kelvin
102+```
103+
104+## New desk
105+
106+Next, we'll create a new `%journal` desk on our ship by forking an existing one.
107+Once created, we can mount it to the unix filesystem.
108+
109+In the dojo of a fake ship:
110+
111+```
112+> |merge %journal our %webterm
113+>=
114+> |mount %journal
115+>=
116+```
117+
118+Now we can browse to it in the unix terminal:
119+
120+```sh
121+cd ~/zod/journal
122+```
123+
124+Currently it has the same files as the `%webterm` desk, so we need to delete
125+those:
126+
127+```sh
128+rm -r .
129+```
130+
131+Apart from the kernel and standard library, desks need to be totally
132+self-contained, including all mark files and libraries necessary to build them.
133+For example, since our app contains a number of `.hoon` files, we need the
134+`hoon.hoon` mark, and its dependencies. The easiest way to ensure our desk has
135+everything it needs is to copy in the "dev" versions of the `%base` and
136+`%garden` desks. To do this, we first clone the Urbit git repository:
137+
138+```sh
139+git clone https://github.com/urbit/urbit.git urbit-git
140+```
141+
142+If we navigate to the `pkg` directory in the cloned repo:
143+
144+```sh
145+cd ~/urbit-git/pkg
146+```
147+
148+...we can combine the `base-dev` and `garden-dev` desks with the included
149+`symbolic-merge.sh` script:
150+
151+```sh
152+./symbolic-merge.sh base-dev journal
153+./symbolic-merge.sh garden-dev journal
154+```
155+
156+Now, we copy the contents of the new `journal` folder into our empty desk:
157+
158+```sh
159+cp -rL journal/* ~/zod/journal/
160+```
161+
162+Note we've used the `L` flag to resolve symbolic links, because the dev-desks
163+contain symlinks to files in the actual `arvo` and `garden` folders.
164+
165+We can copy across all of our own files too:
166+
167+```sh
168+cp -r ~/ourfiles/* ~/zod/journal/
169+```
170+
171+Finally, in the dojo, we can commit the whole lot:
172+
173+```
174+|commit %journal
175+```
176+
177+## Glob
178+
179+The next step is to build our front-end and upload the files to our ship. In the
180+`journal-ui` folder containing our React app, we can run:
181+
182+```sh
183+npm run build
184+```
185+
186+This will create a `build` directory containing the compiled front-end files. To
187+upload it to our ship, we need to first install the `%journal` desk. In the
188+dojo:
189+
190+```
191+|install our %journal
192+```
193+
194+Next, in the browser, we navigate to the `%docket` globulator at
195+`http://localhost:8080/docket/upload` (replacing localhost with the actual host):
196+
197+![globulator screenshot](https://m.tinnus-napbus.xyz/pub/globulator.png)
198+
199+We select our `journal` desk, then we hit `Choose file`, and select the whole
200+`build` directory which was created when we build our React app. Finally, we hit
201+`glob!` to upload it.
202+
203+If we now return to the homescreen of our ship, we'll see our tile displayed, and we can open our app by clicking on it:
204+
205+![tiles screenshot](https://m.tinnus-napbus.xyz/pub/tiles.png)
206+
207+## Publishing
208+
209+The last thing we need to do is publish our app, so other users can install it
210+from our ship. To do that, we just run the following command in the dojo:
211+
212+```
213+:treaty|publish %journal
214+```
215+
216+## Resources
217+
218+- [App publishing/distribution documentation](/docs/userspace/dist/dist) -
219+ Documentation covering third party desk composition, publishing and
220+ distribution.
221+
222+- [Glob documentation](/docs/userspace/dist/glob) - Comprehensive documentation
223+ of handling front-end files.
224+
225+- [Desk publishing guide](/docs/userspace/dist/guide) - A step-by-step guide to
226+ creating and publishing a desk.
content/docs/userspace/full-stack/_index.mdnew file+52
@@ -0,0 +1,52 @@
1++++
2+title = "Full-Stack Walkthrough"
3+weight = 10
4+sort_by = "weight"
5+template = "sections/docs/chapters.html"
6+insert_anchor_links = "right"
7++++
8+
9+#### [1. Introduction](/docs/userspace/gall-2/1-intro)
10+
11+An overview of the guide and table of contents.
12+
13+#### [2. Types](/docs/userspace/gall-2/2-types)
14+
15+Creating the `/sur` structure file for our `%journal` agent.
16+
17+#### [3. Agent](/docs/userspace/gall-2/3-agent)
18+
19+Creating the `%journal` agent itself.
20+
21+#### [4. JSON](/docs/userspace/gall-2/5-json)
22+
23+Writing a library to convert between our agent's marks and JSON. This lets our
24+React front-end poke our agent, and our agent send updates back to it.
25+
26+#### [5. Marks](/docs/userspace/gall-2/4-marks)
27+
28+Creating the mark files for the pokes our agent takes and updates it sends out.
29+
30+#### [6. Eyre](/docs/userspace/gall-2/6-eyre)
31+
32+A brief overview of how the webserver vane Eyre works.
33+
34+#### [7. React App Setup](/docs/userspace/gall-2/7-react-setup)
35+
36+Creating a new React app, installing the required packages, and setting up some
37+basic things for our front-end.
38+
39+#### [8. React App Logic](/docs/userspace/gall-2/8-http-api)
40+
41+Analysing the core logic of our React app, with particular focus on using
42+methods of the `Urbit` class from `@urbit/http-api` to communicate with our
43+agent.
44+
45+#### [9. Desk and Glob](/docs/userspace/gall-2/9-web-scries)
46+
47+Building and "globbing" our front-end, and putting together a desk for
48+distribution.
49+
50+#### [10. Summary](/docs/userspace/gall-2/10-final)
51+
52+Some final comments and additional resources.
content/docs/userspace/gall-guide/10-scry.md+5−4
@@ -154,10 +154,11 @@ can do something like:
154
154
155Previously we discussed custom `mark` files. Such mark files are most commonly
156used when the data might be accessed through Eyre's HTTP API, and therefore
157−required JSON conversion methods. We'll cover such things in part two of the
157+required JSON conversion methods. We cover such things separately in the
158+[Full-Stack Walkthrough](/docs/userspace/full-stack/1-intro), but note that if
158−Gall Guide, but note that if that's the case for your agent, you may wish to
159+that's the case for your agent, you may wish to also have your scry endpoints
159−also have your scry endpoints return data with your custom `mark` so it can
160+return data with your custom `mark` so it can easily be converted to JSON when
160−easily be converted to JSON when accessed from the web.
161+accessed from the web.
161
162
162In some cases, typically with scry `path`s that contain wildcards like the `[%x %blah @ ~]` example above, your agent may not always be able to find the
163In some cases, typically with scry `path`s that contain wildcards like the `[%x %blah @ ~]` example above, your agent may not always be able to find the
163requested data. In such cases, you can just produce a cell of `[~ ~]` for the
164requested data. In such cases, you can just produce a cell of `[~ ~]` for the
content/docs/userspace/gall-guide/12-next-steps.md+11−3
@@ -9,9 +9,11 @@ to start writing your own agent.
9
9
10The things haven't touched on yet are front-end development and integration,
11Eyre's HTTP API for communicating with agents from the web, and dealing with
12−JSON data. A second part to the Gall Guide is coming soon, and will focus
12+JSON data. The [Full-stack Walkthrough](/docs/userspace/full-stack/1-intro)
13−exclusively on those aspects. In the mean time, you can refer to the following
13+covers these aspects of Urbit app development, and it also puts into practice
14+many of the concepts we've discussed in this guide, so you might like to work
15+through that next. In addition to that walkthrough, you can refer to the
14−documents for help writing a web front-end for your app:
16+following documents for help writing a web front-end for your app:
15
17
16- [Eyre's external API reference](/docs/arvo/eyre/external-api-ref) - This
18- [Eyre's external API reference](/docs/arvo/eyre/external-api-ref) - This
17 explains Eyre's HTTP API, through which a browser or other HTTP client can
19 explains Eyre's HTTP API, through which a browser or other HTTP client can
@@ -27,6 +29,12 @@ documents for help writing a web front-end for your app:
27- [The software distribution guide](/docs/userspace/dist/dist) - This covers
29- [The software distribution guide](/docs/userspace/dist/dist) - This covers
28 everything you need to know to distribute apps to other ships. It includes
30 everything you need to know to distribute apps to other ships. It includes
29 details of bundling a web front-end and serving it to the user in the browser.
31 details of bundling a web front-end and serving it to the user in the browser.
32+- [The HTTP API guide](/docs/userspace/http-api-guide) - This is a reference
33+ and guide to using the `@urbit/http-api` NPM module.
34+- [The Sail guide](/docs/hoon/guides/sail) - Sail is a domain-specific language
35+ for composing XML structure in Hoon. It can be used to compose front-ends for
36+ Urbit apps directly in agents, as an alternative approach to having a
37+ separate Javascript app.
30
38
31In addition to these documents about creating a web-based user interface for
39In addition to these documents about creating a web-based user interface for
32your app, there are some other guides you might like to have a look at:
40your app, there are some other guides you might like to have a look at:
content/docs/userspace/gall-guide/7-sur-and-marks.md+8−8
@@ -282,12 +282,13 @@ arm in the previous example could test for it instead of `%noun` like so:
282Note how `%todo-action` will be resolved to `/mar/todo/action.hoon` - the hyphen
283will be interpreted as `/` if there's not already a `/mar/todo-action.hoon`.
284
284
285−This simple mark file isn't all that useful. Typically, you'd add `json` arms to
285+This simple mark file isn't all that useful. Typically, you'd add `json` arms
286−`grow` and `grab`, which allow your data to be converted to and from JSON, and
286+to `grow` and `grab`, which allow your data to be converted to and from JSON,
287−therefore allow your agent to communicate with a web front-end. Front-ends,
287+and therefore allow your agent to communicate with a web front-end. Front-ends,
288−JSON, and Eyre's APIs which facilitate such communications will be covered in a
288+JSON, and Eyre's APIs which facilitate such communications will be covered in
289−forthcoming part two of the Gall guide. For now though, it's still useful to use
289+the separate [Full-Stack Walkthrough](/docs/userspace/full-stack/1-intro),
290+which you might like to work through after completing this guide. For now
290−marks and understand how they work.
291+though, it's still useful to use marks and understand how they work.
291
292
292One further note on marks - while data from remote ships must have a matching
293One further note on marks - while data from remote ships must have a matching
293mark file in `/mar`, it's possible to exchange data between local agents with
294mark file in `/mar`, it's possible to exchange data between local agents with
@@ -384,8 +385,7 @@ Mark files:
384- Messages passed between agents on a local ship don't necessarily need mark
385- Messages passed between agents on a local ship don't necessarily need mark
385 files in `/mar`.
386 files in `/mar`.
386- Mark files are most commonly used for converting an agent's native types to
387- Mark files are most commonly used for converting an agent's native types to
387− JSON, in order to interact with a web front-end (which we'll cover in part two
388+ JSON, in order to interact with a web front-end.
388− of the Gall guide).
389
389
390Permissions:
390Permissions:
391
391